GPU Cluster Design and Deployment
We design and deploy GPU clusters sized to your actual workload, validated under real load before a production training run is what finds the capacity gap.
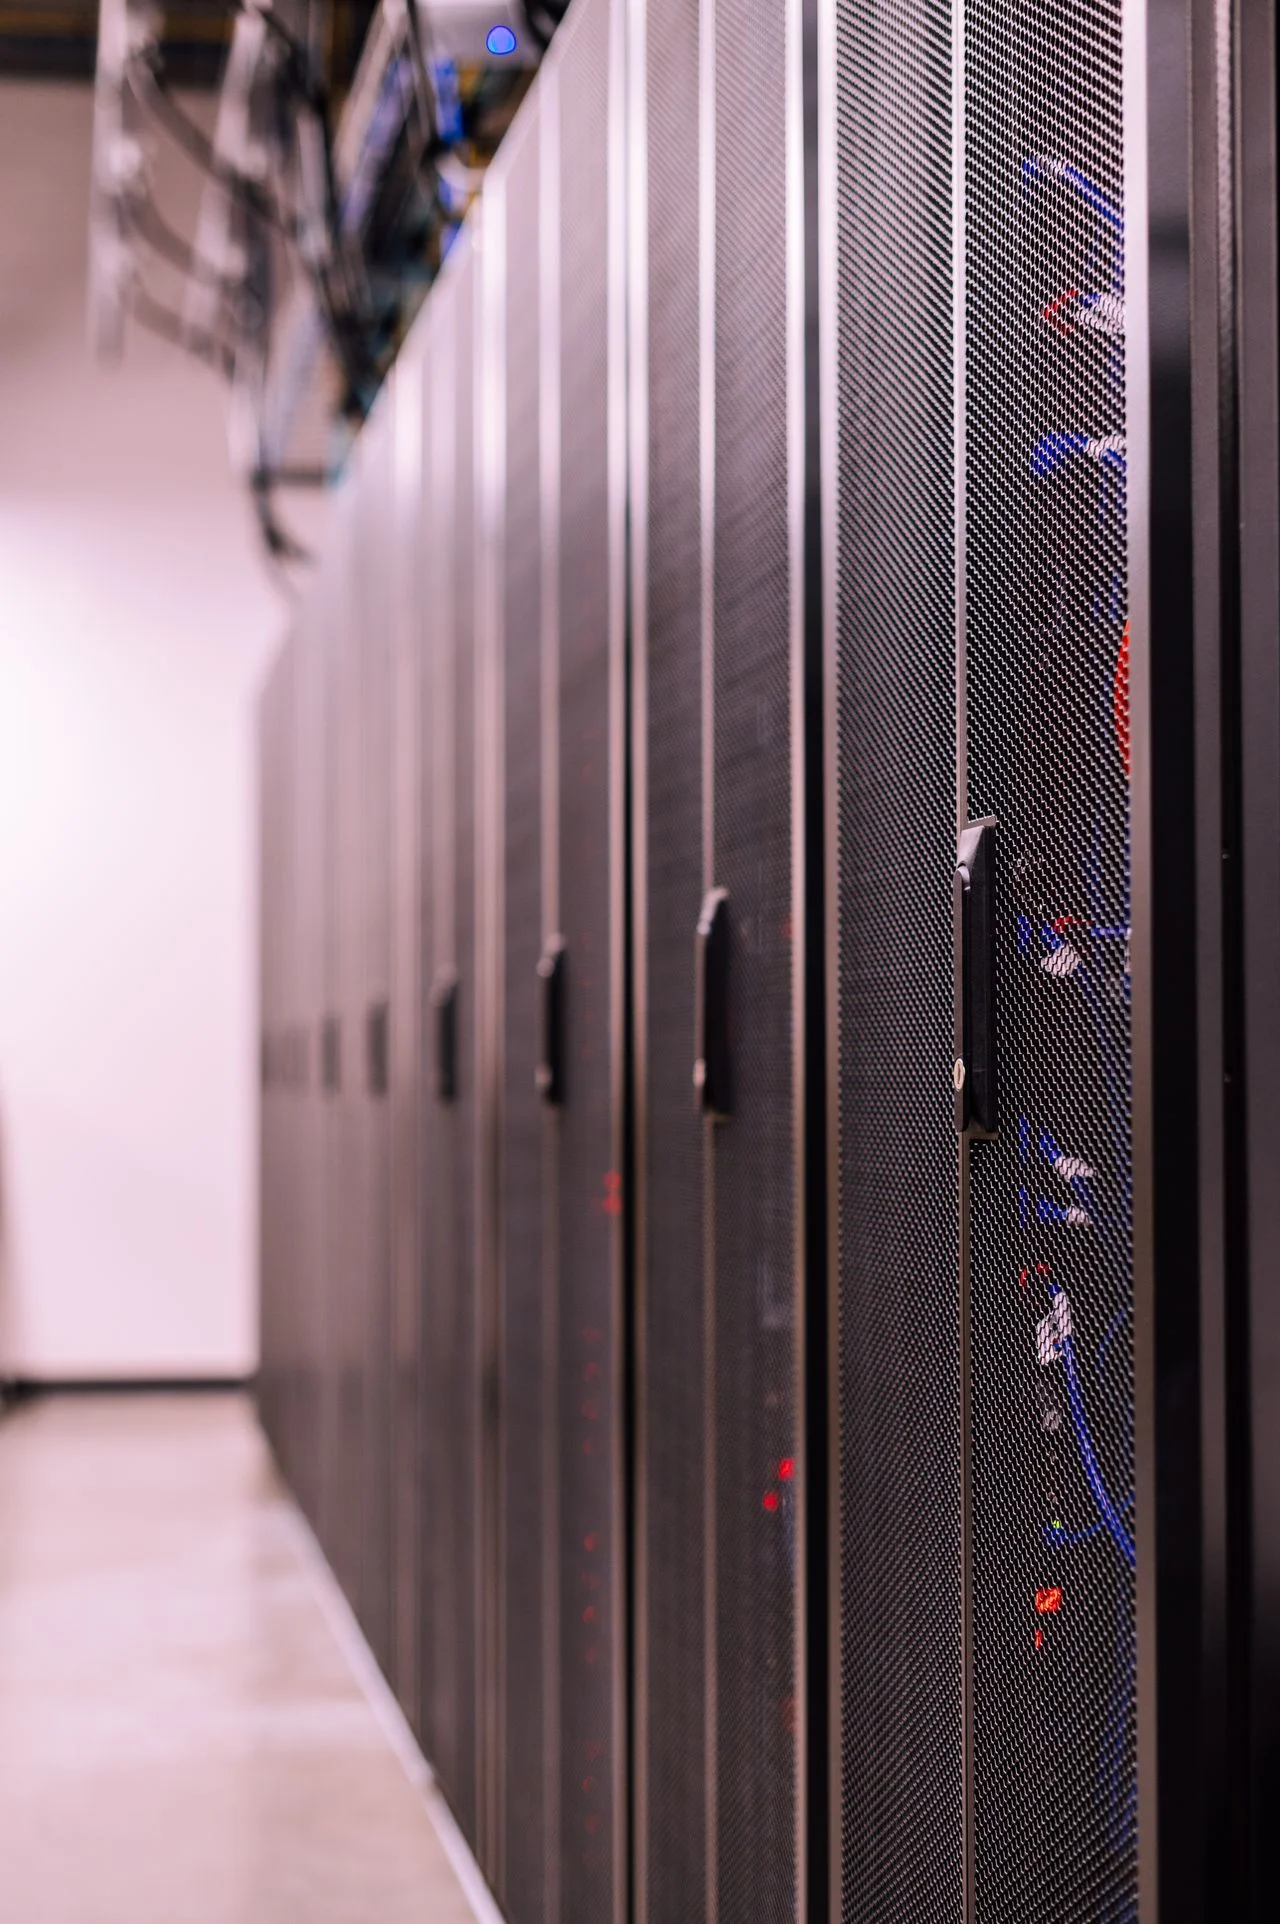
We design and deploy AI-ready data center infrastructure with certified uptime standards and audited capacity planning, so your training runs don't stall on infrastructure that wasn't built for the load.
AI workloads don't fail gracefully on infrastructure built for a different era of compute. A GPU cluster that runs hot, a network that can't keep up with interconnect demand, or a power system that wasn't sized for the load doesn't just slow a training run, it stops it. We build the infrastructure layer for the workload you actually have, not the one a generic data center reference architecture assumes.
We architect data center infrastructure around your actual AI workload profile, power density, cooling needs, and interconnect requirements included from the start.
GPU cluster deployment and high-performance networking go in built to the capacity plan, validated under real load before it's your production training run finding the bottleneck.
Every environment meets defined security and compliance standards, audited before it takes on workloads, not patched after an incident finds the gap.
We stay engaged through MLOps and infrastructure automation, so scaling capacity is a planned decision, tracked against real utilization, not a reactive scramble when a training run gets throttled.
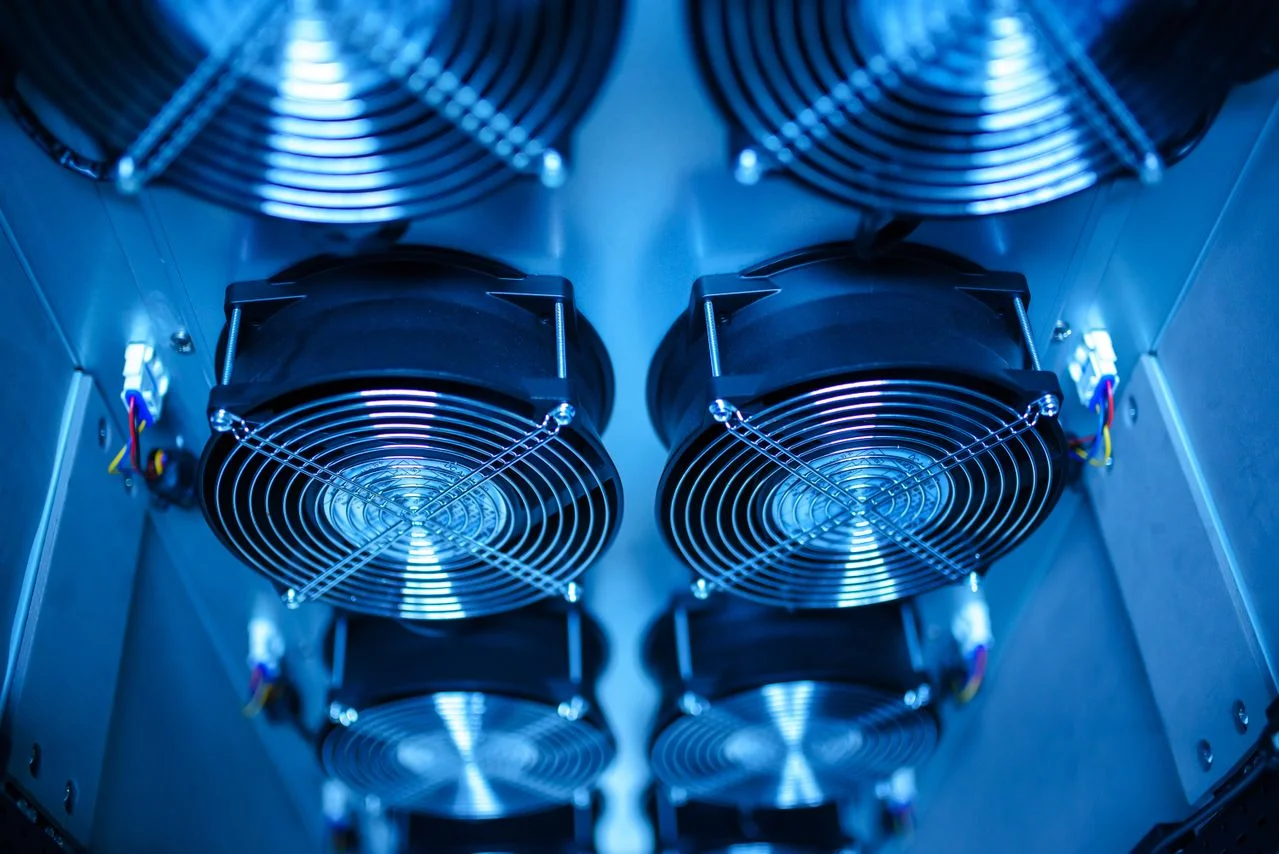
From thermal planning to high-speed interconnects, we engineer enterprise AI data centers with maximum uptime and efficiency.
We design and deploy GPU clusters sized to your actual workload, validated under real load before a production training run is what finds the capacity gap.
We architect data center facilities around the power density and cooling profile AI workloads actually require, not a general-purpose data center spec retrofitted after the fact.
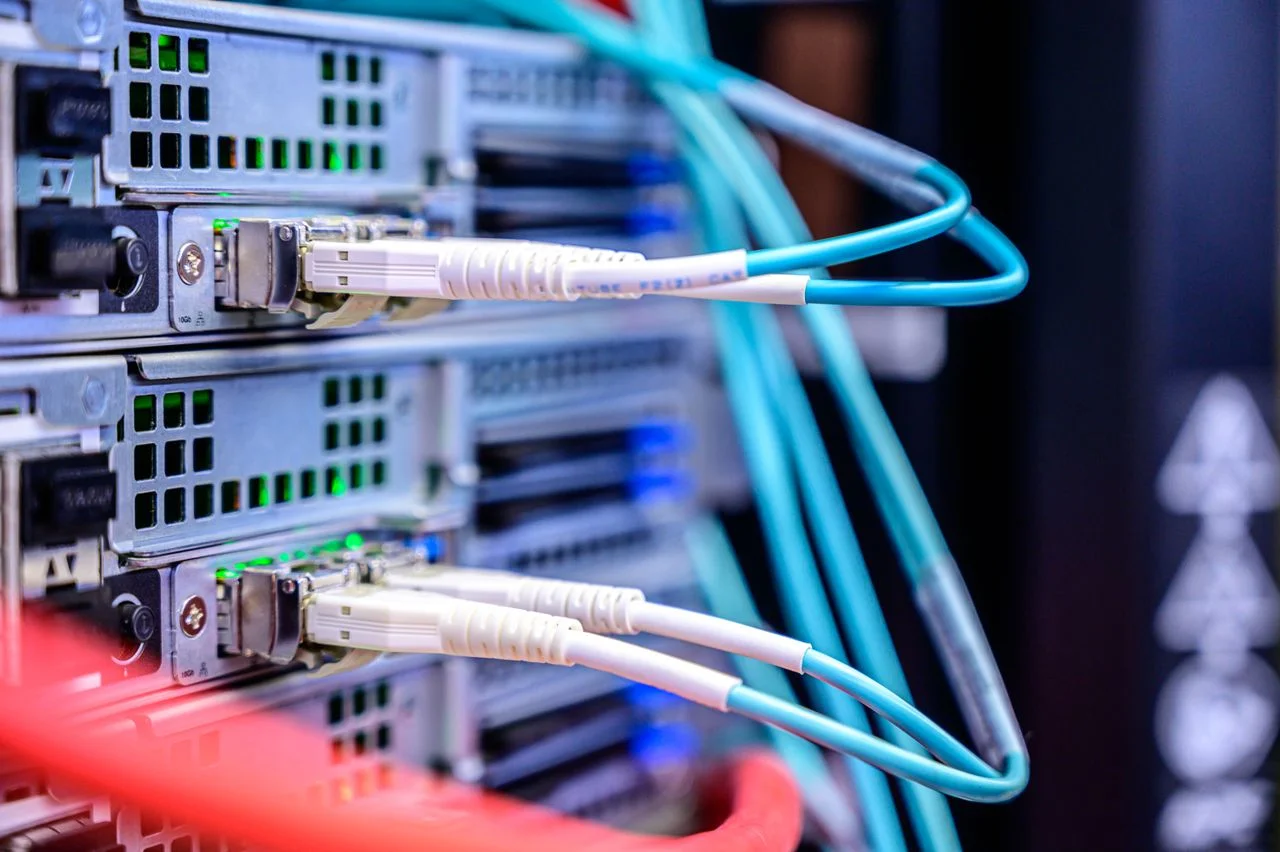
We build the networking layer that keeps GPU-to-GPU interconnect from becoming the bottleneck a compute upgrade was supposed to fix.
We design power delivery and cooling systems engineered for AI's density and thermal load, audited against the capacity your cluster actually draws.
We automate the infrastructure operations around model training and deployment, with human oversight on the capacity decisions that shouldn't be fully automated.
We build physical and network security controls audited to defined compliance standards, closing the gap that generic IT security assumptions leave open in an AI-scale facility.

We build the capacity models that tell you when you're actually going to run out of headroom, tracked against real utilization instead of a rough estimate made at initial deployment.
Connecting consulting to growth & impact, bringing together news, insights, articles, and decisions that shape the future.

Power density, cooling, and interconnect requirements for AI training don't match a generic data center reference architecture. What actually needs to change.

A look at the load-validation step most cluster deployments skip until a production training run finds the gap.
Why thermal and power density, not compute itself, is increasingly the constraint on AI infrastructure scale.

How infrastructure automation handles routine scaling while keeping human oversight on the decisions that shouldn't be automatic.
Everything you need to know about FWC's ai & data center infrastructure engineering, consulting, and deployment practices
We design around your actual workload profile in the "Design" stage, and clusters get validated under real load before deployment, so a capacity gap surfaces during planning instead of during your first production training run.
MLOps and Infrastructure Automation handles routine scaling operations, but capacity decisions above a defined threshold get human oversight, so automation accelerates operations without quietly committing budget on its own.
It's genuinely different. AI workloads run at a power density and thermal load that a general-purpose data center spec usually isn't sized for, which is why Power and Cooling Optimization is one of our seven core offerings, not an afterthought bundled into a generic build.
Data Center Security and Compliance builds physical and network controls audited against defined standards before the environment takes on workloads, not retrofitted after a security review flags a gap.
Capacity Planning and Scaling Advisory tracks your real utilization and builds a model around it, so you know when you're actually going to run out of headroom instead of relying on a rough estimate made at initial deployment.
We stay engaged through MLOps and infrastructure automation as your needs scale, so growing capacity is a planned decision tracked against real usage, not a reactive scramble the first time a training run gets throttled.
Let’s turn business
challenges into opportunities.
Ask FWC AI anything
Instant keyboard navigation across all 15 services, 10 industries, 8 AI systems, and enterprise careers.